How Hebbia evals long-horizon agents for finance teams
With Adithya Ramanathan, Head of Applied AI
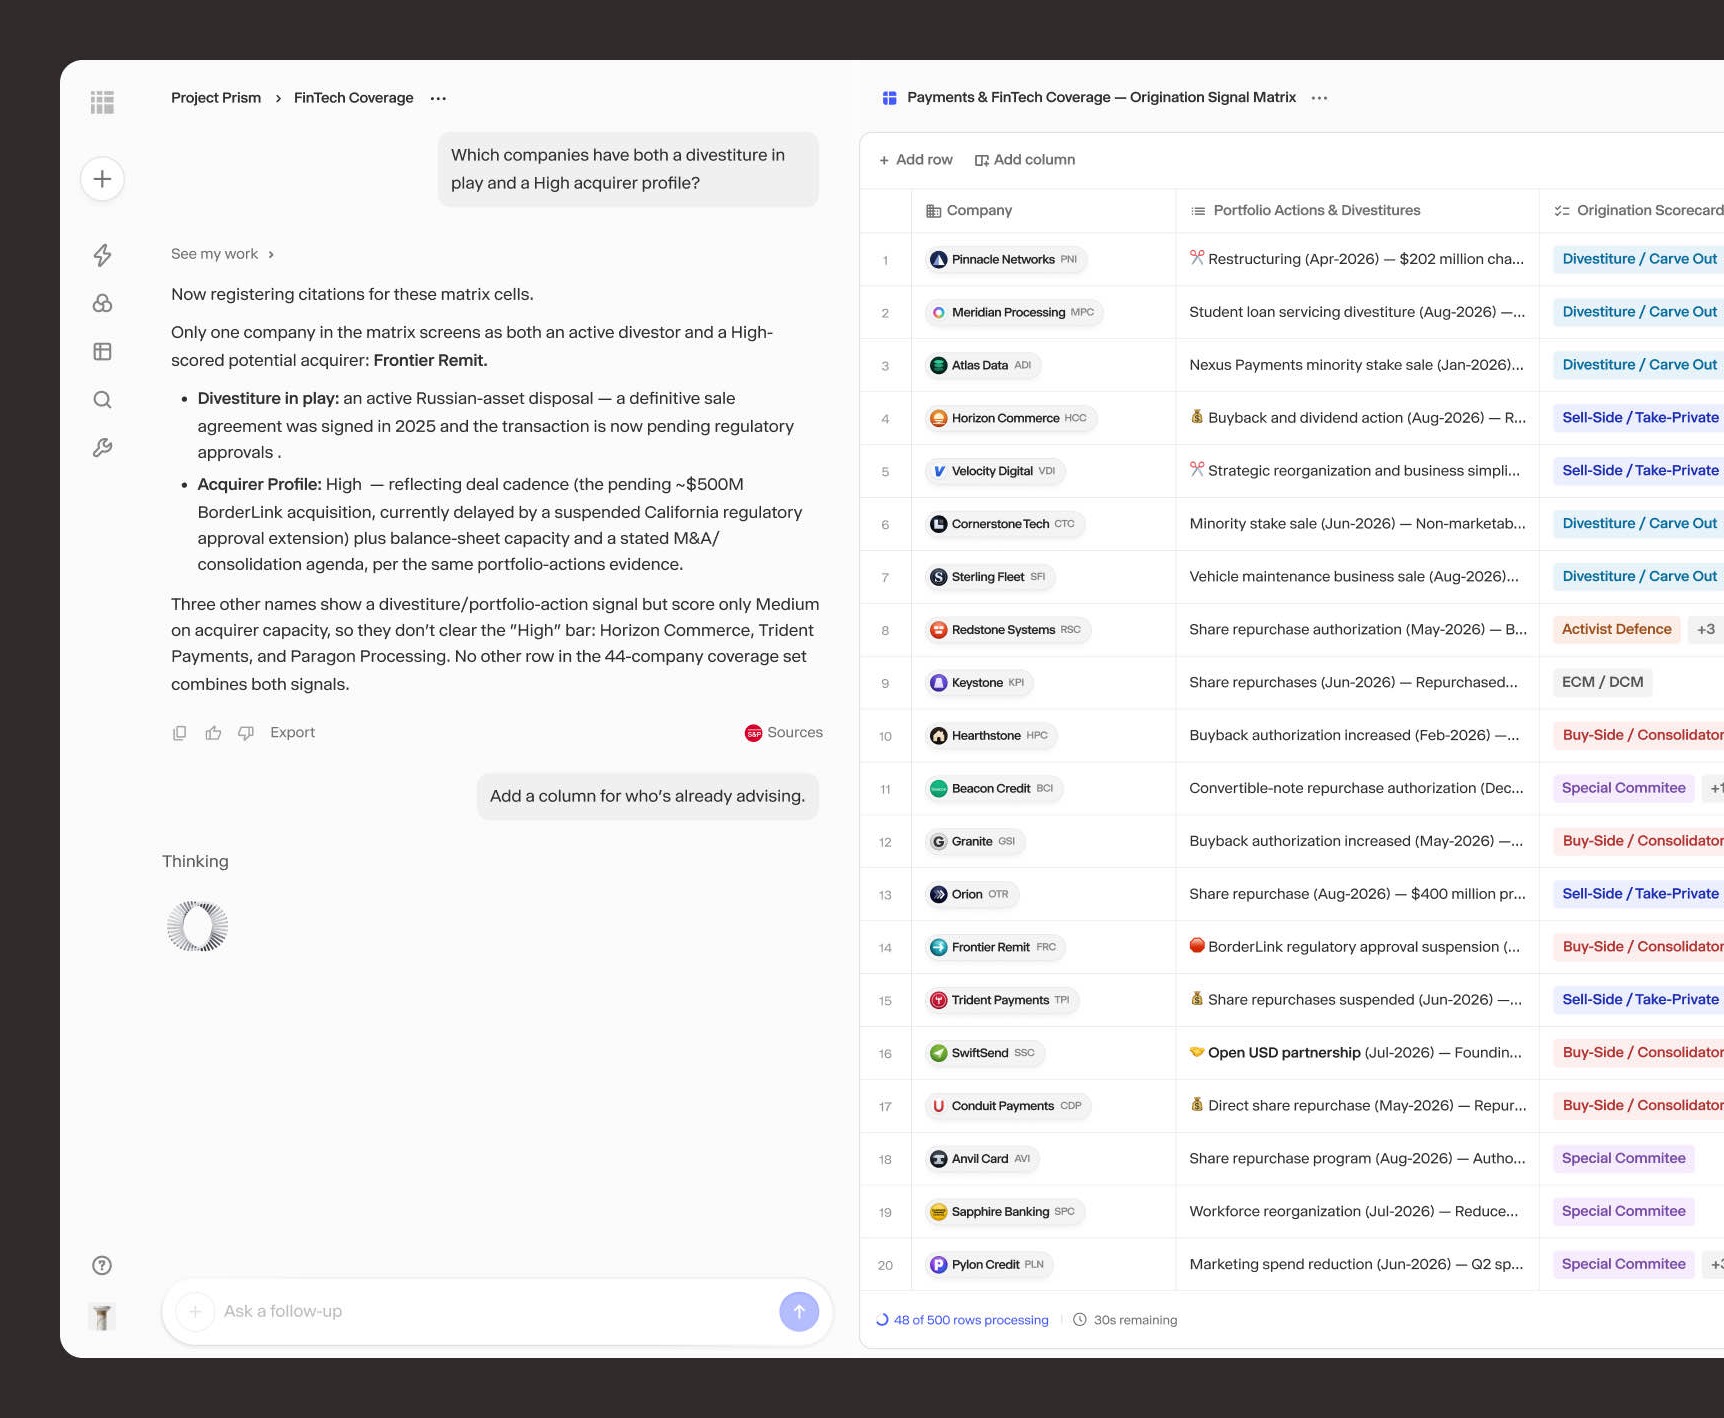
Hebbia is an AI research and diligence platform for finance teams, used in investment banking, private equity, public equities, and credit. It builds and serves agents that automate workflows for customers in these industries, with a focus on outcome generation for things like PowerPoints, diligence memos, and spreadsheets.
Adithya is Hebbia's Head of Applied AI, responsible for the engineering teams building the agentic parts of the product, and for its applied research team.
Building evals in house
Like many companies, Hebbia went through every iteration of what measuring AI looks like. They graduated from the traditional machine learning world into agents, built golden sets and golden queries, and then tried to stand up the eval tooling and infrastructure themselves.
That meant taking on infrastructure work the team wasn't able to prioritize, and the result was that they weren't as efficient as they could be at generating eval results and improving their agents.
Braintrust helps us stop focusing on the minutiae of infrastructure associated with evaluations and just focus on the results that we care about.

Before Braintrust
Effort spent on infrastructure
Optimizing agent behavior with a smaller model
Hebbia's work starts with defining what its eval datasets look like and making sure they capture the right complexity of tasks. The team is constantly looking for the hard things its agents fail at, so they know where to hill climb.
With an agent, the input space is much larger than in traditional machine learning. It's all the software the agent interacts with, the way these workflows are arranged, and the prior inference calls the agent makes, which compound.
For Hebbia, the thing being optimized isn't a single outcome, but how efficiently the agent produced that outcome, how explainable the process was, and what it cost, where cost isn't the token spend alone but a factor of cache hit rate and output volume.
Our optimization problem isn't just make eval number go high. If I can make it five points better but it costs a thousand percent more, I might need to take the sacrifice of making it 4.9 points better at a 1.1x increase in cost.
Capturing that battery of inputs alongside traces is what lets the team optimize those outcomes through evals.
That showed up concretely in PowerPoint generation, the primary means of content for much of Hebbia's customer base. The team wanted to accomplish similar quality outcomes with a less-expensive, lower intelligence model. But they found that the smaller model would make more mistakes and struggle to course correct, whereas a higher intelligence model might make the same mistakes but solve them faster.
To do this, they shifted to a sub-agent approach with cleaner context and more awareness of common PowerPoint pitfalls, which improved performance relative to the larger model.
Honing this approach meant using evals to identify where in a roughly 40-step process the agents were breaking down. Once they did so, Adithya and team were able to build their agent on the cheaper model without sacrificing the quality of the PowerPoint outputs.
Traces inside an automatic optimization loop
Hebbia's consumption of traces increasingly happens inside its own eval loop, rather than being reviewed by hand.
When a new model drops, the team stands it up in its infrastructure and the auto-eval loop kicks off. It tests the model, perturbs and runs multiple versions of each example in the eval framework, then examines and compares the traces to suggest modifications to tool descriptions, system prompts, skills, and even the agent as a whole.
Where Braintrust has been really valuable is in driving that great repository of comparative traces and the comparative capability. Our research loop is able to plug in and make the call to our Braintrust infrastructure to look at the grade and outcome and drive the optimization work.
The team uses the Braintrust MCP and CLI to enable this automation and optimization loop. If you're an AI-native company, Adithya argues, it's part of the mandate for every engineer to be capable of writing, executing, and operating evals.
Every piece of code in the repository gets attached with the relevant tracing decorators, so it's already flowing into Braintrust and already plugged into the optimization loop. From there, as new models come out, Hebbia can drive improvement and maintenance without it becoming a burden on the engineer.
Evals for regulated industries
Hebbia's customers operate in highly data-sensitive and regulated environments, often working with material nonpublic information. Any recorded observability or tracing needs to be stored in well-secured data environments.
Adithya and team wanted a platform configurable against those demands, and one it could bundle into the cloud package it builds for each tenant. Braintrust's BYOC deployment model enabled this from the start.
Braintrust also allows single-tenant customers to manage their own encryption keys, so the same data security guarantees hold all the way through while the customer gets better agent observability and evals. And if a customer isn't comfortable with the deployment, or needs to change their security framework, it can easily be turned off.
Inference cost efficiencies at larger scale
At Hebbia's usage and scale, days of inference matter for the company's unit economics, so anything that produces a more token-efficient product helps determine what the team ships.
Braintrust has really helped drive a lot of our work in getting to a place where we have a measurable, hill-climbable score, and connecting into systems where we're able to automate that hill climb as well.
Part of driving this cost efficiency is speed. Where the team previously spent a week or two to reach a calculation of where an agent was, where it could be, and what savings that represented, they can now do that on virtually day one with Braintrust. They get early access to a model, run it through the eval process, and immediately start to understand the new cost implications.
Key takeaways
- Grade the process and the output. In a long-horizon agent task the intermediate outputs are things your user consumes, so you need to understand them alongside the final output.
- Let your team focus on the product. Engineers should spend their time building, not on the infrastructure work required to support observability.
- Make writing evals part of every engineer's job. Remove the reasons they can't by automating the entire workflow.
Thank you to Adithya for sharing Hebbia's story.
Read more customer stories
Malte Ubl, CTO
“We didn't realize we needed deep observability until Braintrust.”
Zach Tessler & Ally Cody, Engineering Management
“We're all proud of what we've put out there and a lot of that is powered by Braintrust.”
Mauricio Wulfovich, Staff Machine Learning Engineer
“Braintrust CLI experiments ensure our agents produce the best work.”